About
I am Xiang Wen. I am working toward real-time interactive worlds: environments generated as you move through them, that change because of what you did. The project carrying that now is EverWorld, real-time interactive spatial video models. You explore a scene, act on its objects and talk to its characters, and your input shapes what happens next.
Almost everything a generative model produces today is finished before anyone sees it. You write a prompt, you wait, you watch the result. The version worth building is the one where the world is still being produced while you are inside it. That needs a model holding a consistent world rather than a consistent clip, and it needs that model to answer fast enough to feel like a response. Neither is solved.
The problem does not belong to one field. It needs generation quality from generative AI and diffusion models, spatial consistency and real-time rendering from computer graphics, and geometry and camera understanding from 3D vision. I have shipped work in all four over the past decade, and my honest read is that the hard parts do not sit inside any of them. They sit in the seams, where a diffusion model has to respect geometry it was never taught, or a renderer has to accept something a network hallucinated.
How I got here
I started at NetEase Fuxi in 2016 on game agents, making an AI fight like a person rather than a script that chases you. We built a hierarchical reinforcement learning framework that split "when to engage and with whom" from "how to fight". It shipped, and it taught me something I have never forgotten: get the reward function slightly wrong and the agent will find a way through it that you never imagined.
In the same period I worked on music-to-dance generation, AI motion capture, and expression retargeting. None of these has a unique correct answer. The same piece of music supports a hundred reasonable dances, and no loss function will tell you which one is right. That is where I first understood that generation and discrimination need fundamentally different evaluation.
At ByteDance from 2020 the question became production scale. A large game ships an enormous amount of narrative animation every year while artist capacity grows linearly. We reframed character customization as a search problem in latent space, and used semantic graph matching to assemble narrative animation automatically. The lasting lesson was that whether a model can enter a production pipeline depends on how it fails, not on how it succeeds. A model with a high average and occasional catastrophes is unusable. A model with an ordinary average and a stable floor will ship.
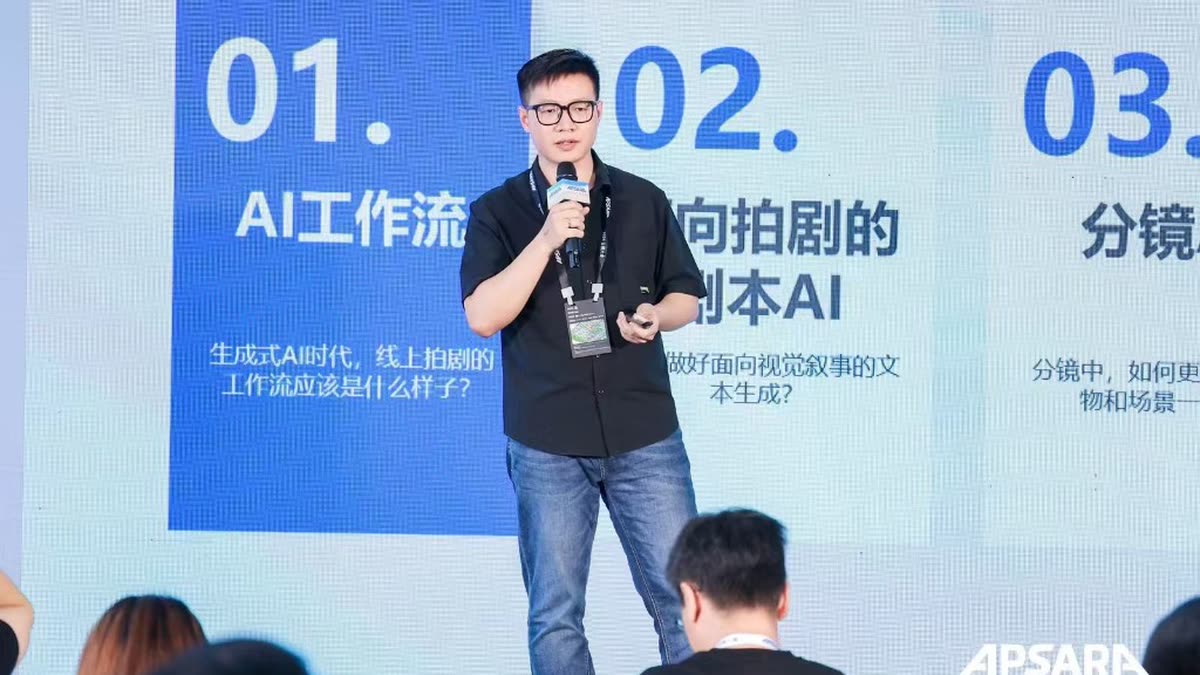
At SkyReels AI in 2023 I ran a business rather than an algorithm team for the first time, as its business lead and CTO. The product asked whether someone who knows nothing about filmmaking could still turn a story into a short drama. Script generation, storyboarding, shot planning, video generation: four stages, each needing its own model, protocol, and evaluation. It was also where I first ran a full video post-training loop end to end, and first saw the uncomfortable gap between real user preference and offline metrics.
What I am working on
Most of it goes into EverWorld. It is planned as three versions, and each one changes who the person in the scene is:
- Play (1.0), you are a participant. Interactive scene generation in a room-scale scene: ring the bell, unfold the map, and the scene responds. Sound and picture keep generating, and your changes persist when you look away and return.
- Compose (2.0), you are a creator. Large-scale spatial orchestration: describe a larger scene, shape connected streets, docks and a lighthouse, create interactive objects, edit the layout and rules, then step inside to try the space you designed.
- Evolve (3.0), you are a collaborator. Agent-driven scene evolution: talk to your guide and change the route mid-conversation, while characters remember their experience, weigh possible actions and pursue their goals together.
The three versions extend one shared foundation rather than replacing each other: persistent state and memory, spatial perception and geometry, multimodal understanding, and joint audiovisual generation. The rule that runs through all of it is plan first, then act. Candidate actions are rolled out in isolated branches, evaluated, and only the selected one is executed live. Planning never modifies the scene the player is standing in.
At Tencent Hunyuan I lead post-training for anime-domain video generation. Three threads: generation quality, a unified architecture handling text, image, multi-reference, and editing in one model, and inference acceleration.
That last thread is not a footnote. Interactive content is gated on latency before it is gated on quality. A model that produces a beautiful clip in ninety seconds cannot be stepped into. Most of the distance between where video generation sits now and where interactive content needs it is measured in milliseconds, not in benchmark points.
The open question I keep returning to is where the evaluation signal comes from. Nearly ten years separate the reward functions I hand-wrote for game agents from the preference models I work with now, and the underlying problem has barely moved:when "good" cannot be defined precisely, how do you construct a signal honest enough to steer a very large model. Interaction makes it harder, because what gets judged is no longer an artifact but a response.
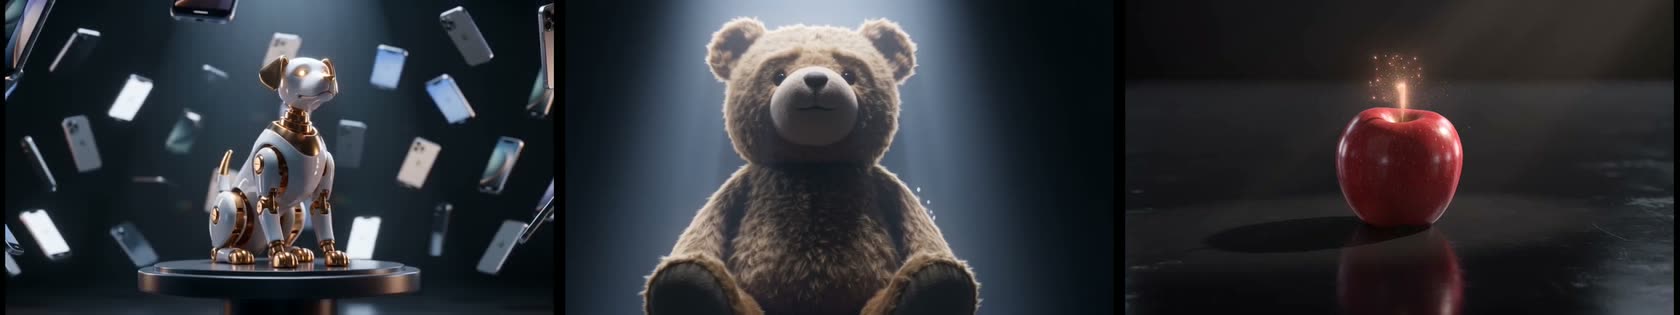
On the side I am building a pipeline that turns papers into narrated videos. The reason is simple. The hard part of reading a paper was never the math, it was building intuition for the method as a whole, and video does that far better than text. The frames above came out of it.
If you want to build EverWorld's models, runtime, evaluation or interactive experiences with me, or think I have the wrong end of any of this, I would like to hear from you. Contact.